Anthony Saviano
One model at a time
Soundbox keeps one model in VRAM at a time. In one run from the server log, a job took 15.1s with a model load and 1.7s without one.
Updated
The Soundbox catalogue has 65 models, and the app keeps one of them in VRAM at a time. Loading a new model unloads the old one. The Models page says this in its subtitle. It's why the first call to a model is slow and the second isn't, why the stdio bridge won't load models, and why the VRAM column sits next to the Load button.
This post covers that rule and how many seconds it costs. For which model to pick, see the Models page. For how audio.cpp works underneath, see what audio.cpp replaced.
The numbers
The catalogue in server/src/models/audiocpp_models_catalog.json has four
models verified end to end: weights downloaded, loaded, generated and decoded
on a real machine. The other 61 are catalogued but untested, and each stays
hidden until you enable it in Settings. GET /api/models returns the four plus
whatever you've switched on. The machine below has enough extras enabled to
show fifteen rows. The Status column marks which ones are verified, so an
untested row doesn't look the same as a tested one.
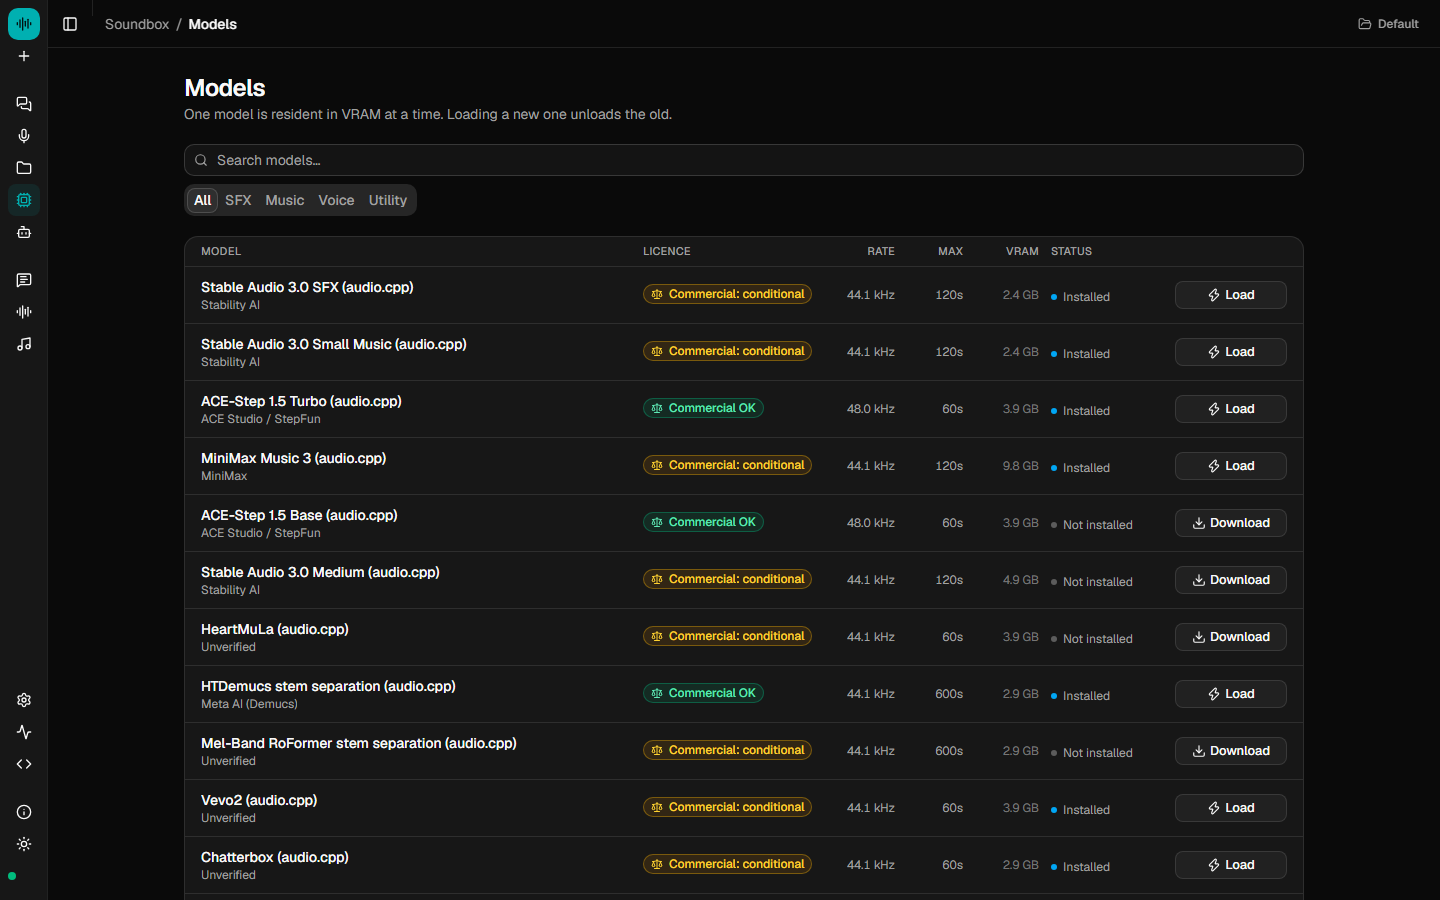
Look at the VRAM column. Stable Audio 3.0 SFX needs 2.4 GB. ACE-Step 1.5 Turbo needs 3.9 GB. MiniMax Music 3 needs 9.8 GB. Further down, a MiniMax H3 entry is estimated at 35.9 GB, with the same Download button as the rest. On an 8 GB card you can run the first two, the third won't fit, and the fourth needs a much bigger machine.
No consumer card can hold all 65 at once, so Soundbox loads one and prints each model's VRAM next to its name. Licences are shown the same way, before the download, so you find out what will stop you before you've spent the bandwidth.
What the log shows
Here are two jobs on the same model, half a minute apart, from the server log. The app shows this log on the Activity page.
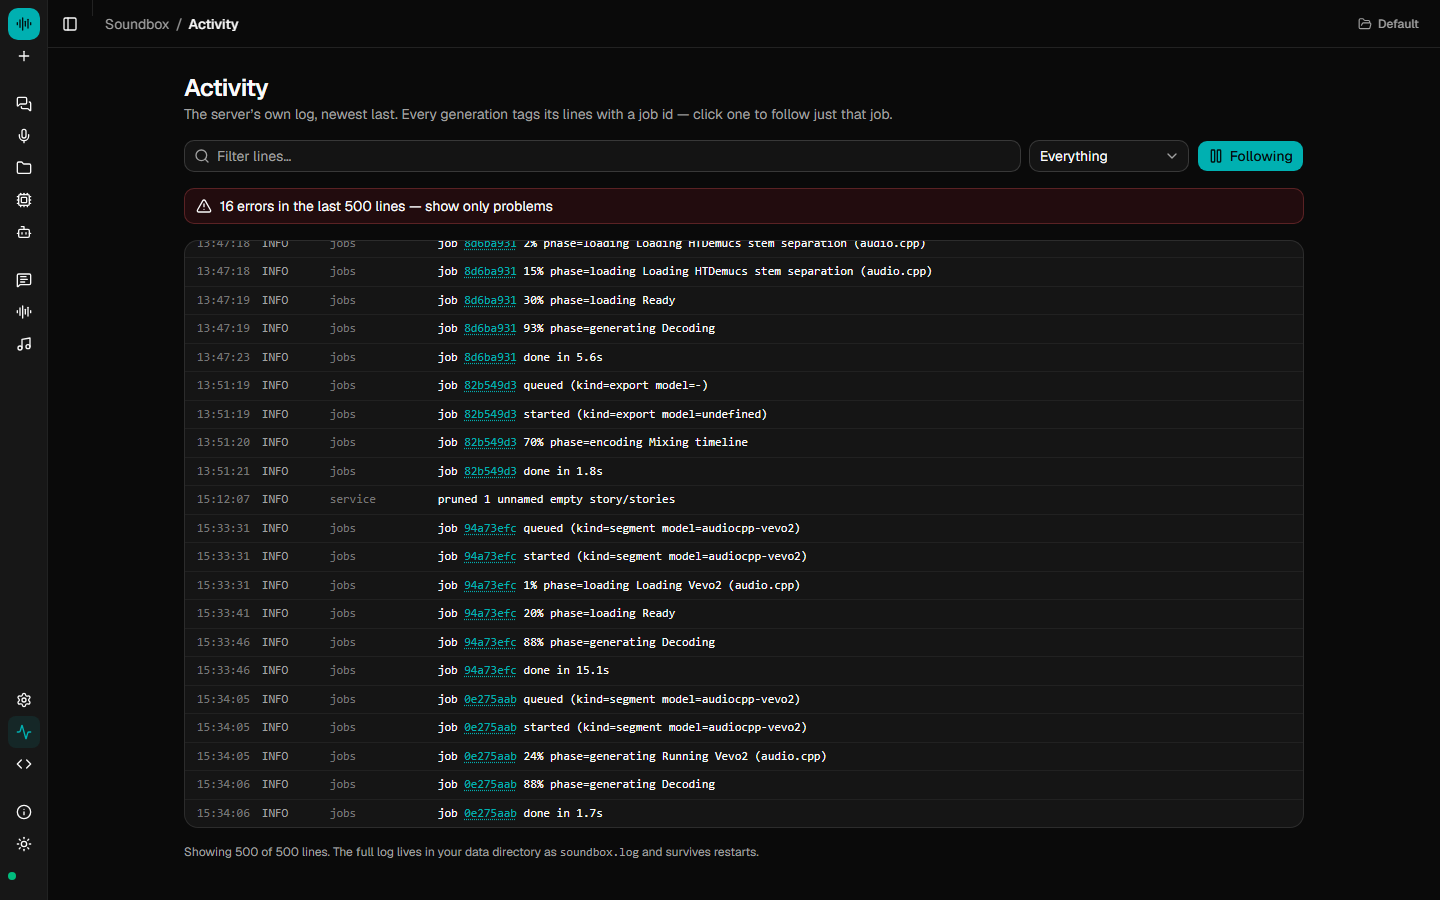
The first job spends ten seconds in phase=loading before it reaches Ready,
then decodes, and finishes in 15.1s. The second has no loading phase. It goes
straight to phase=generating Running Vevo2 and finishes in 1.7s. The model,
machine and afternoon are the same. The only difference is that the weights
were already loaded the second time.
That's one run on one machine, not a benchmark. Your card, model and clip length will change the numbers. What carries over is that you pay the load once each time a model becomes resident, and after that you're only paying for generation. So if a session feels slow, change the order of your work. Do all the sound effects, then all the music, then all the voice lines, and you pay the load three times instead of thirty.
Models do unload when idle. auto_unload_minutes defaults to 10 in
server/src/config.ts, so a model you've stopped using gives its VRAM back
before you quit the app. If you come back after lunch, you pay the load again,
and you can see it in the log.
Why the bridge won't load a model
The stdio MCP bridge is for clients that can't speak streamable HTTP. It's a thin proxy to a running Soundbox server. Its header comment gives the reason: one GPU, one process holding the weights. If the server isn't running, the tools return an error that tells you what to do. They don't start a second copy, because a second copy is a second process that thinks it owns the VRAM, and whichever of the two asks second fails.
Connecting an agent is covered in point your agent at Soundbox and in docs/MCP.md.
Why not keep several loaded
The other option is to keep several models resident and let the driver manage
it. On a consumer card that doesn't just slow down. It runs out of memory
partway through a generation, and your agent gets an error it can't explain.
A comment in server/src/models/manager.ts names the target hardware as a
16 GB consumer card, so loading model B unloads model A first. You get a
ten-second load that shows up in the log and on a page that says what's
resident, instead of a crash.
Everything runs on your own hardware, works offline once the weights are downloaded, and uploads nothing. Soundbox itself is MIT.